Top 8 Data Anonymization Tools: Safeguarding Sensitive Data
Protecting Sensitive Data: Why Data Anonymization Matters
In our review, we weighed each tool against the requirements that decide enterprise purchases: which masking types it supports, whether it covers GDPR, CCPA, and HIPAA obligations, how it prices, and how much engineering effort a rollout demands. The result below is a decision aid, not a feature brochure — if you only read the table, you’ll already know which two or three tools to shortlist. Enterprise data anonymization has become a substantial software category as large organizations seek to make production-like information usable without exposing real identities. Market research estimated global data-masking vendor revenue at approximately $1.2 billion in 2025, with a forecast of $3.78 billion by 2034 and a compound annual growth rate of 13.6% (market analysis).
| Tool | Masking types | Platform support | Compliance coverage | Pricing model | Best-fit team |
|---|---|---|---|---|---|
| ARX | Static (k-anonymity, l-diversity, t-closeness, differential privacy) | Java-based, cross-platform | GDPR, HIPAA support | Free, open-source | Researchers, dev/QA teams |
| Privacera | Static + dynamic masking, policy enforcement | Snowflake, AWS, Azure, GCP, Hadoop | GDPR, CCPA, HIPAA workflows | Quote-only, enterprise tier | Enterprise compliance teams |
| IBM InfoSphere Optim | Static masking, subsetting, archiving | IBM ecosystem, multi-source | GDPR-oriented workflows | Quote-only (high) | Enterprises on IBM stack |
| Informatica Persistent Data Masking | Static + dynamic, FPE | Cross-platform databases | GDPR, CCPA, HIPAA | Custom quote | Enterprise compliance teams |
| Delphix Dynamic Data Platform | Dynamic masking on virtual copies | Broad DB + app support | GDPR-oriented workflows | Quote-only | Dev/test platform teams |
| Microsoft SQL Server Data Masking | Dynamic only (column-level) | SQL Server only | Supports GDPR/CCPA/HIPAA efforts | Included with SQL Server | SQL Server dev/QA teams |
| MOSTLY AI | Synthetic data generation | Cloud-based, API | Supports GDPR/CCPA data sharing | Subscription | AI/analytics teams |
| Oracle Data Masking & Subsetting | Static masking + subsetting | Oracle Database/EM | GDPR/CCPA/HIPAA workflows | Tied to Oracle licensing | Oracle DBA teams |
Three buyer profiles emerge from that table. Enterprise compliance teams with regulated workloads and dedicated governance staff should start with Privacera or Informatica Persistent Data Masking. AI and analytics teams that need usable datasets without PII should look at MOSTLY AI. Development and QA teams that want low-cost coverage are served by ARX, SQL Server Data Masking, or Delphix, depending on their database estate. DLA Piper reported that European authorities received an average of 363 personal-data-breach notifications per day during the period covered by its January 2025 survey, up from 335 per day in the preceding comparison. A later survey reported an average of 443 notifications per day between January 28, 2025, and January 27, 2026 (GDPR enforcement survey).
How We Picked These Data Anonymization Tools
We compared the tools across five practical criteria: privacy model support, enterprise scalability, compliance coverage, integration with existing database systems and workflows, and pricing transparency. These factors help buyers assess whether a tool fits their data, governance requirements, and team capacity.
For open-source entries like ARX, community activity and documentation are relevant considerations. For commercial platforms, buyers should assess deployment requirements, integrations, support, and the resources needed for implementation using the information available from each vendor.
Three things warrant particular attention in a buyer’s evaluation: audit trails for masking operations, referential integrity (which affects whether test data remains useful), and a clear account of the anonymization approach. Each tool below has a specific use case and limitations to weigh.
1. ARX Data Anonymization Tool
ARX is a powerful open-source data anonymization tool designed to help organizations protect sensitive personal information while preserving data utility. It offers a range of privacy-enhancing technologies, making it a valuable asset for researchers, developers, and businesses working with sensitive data. ARX excels in providing a user-friendly graphical interface, enabling even non-technical users to perform complex anonymization tasks with ease. This, combined with its many features and active community support, makes it a top contender among data anonymization tools. Its focus on compliance with data protection regulations like GDPR and HIPAA further solidifies its position as a go-to solution for privacy-conscious organizations.
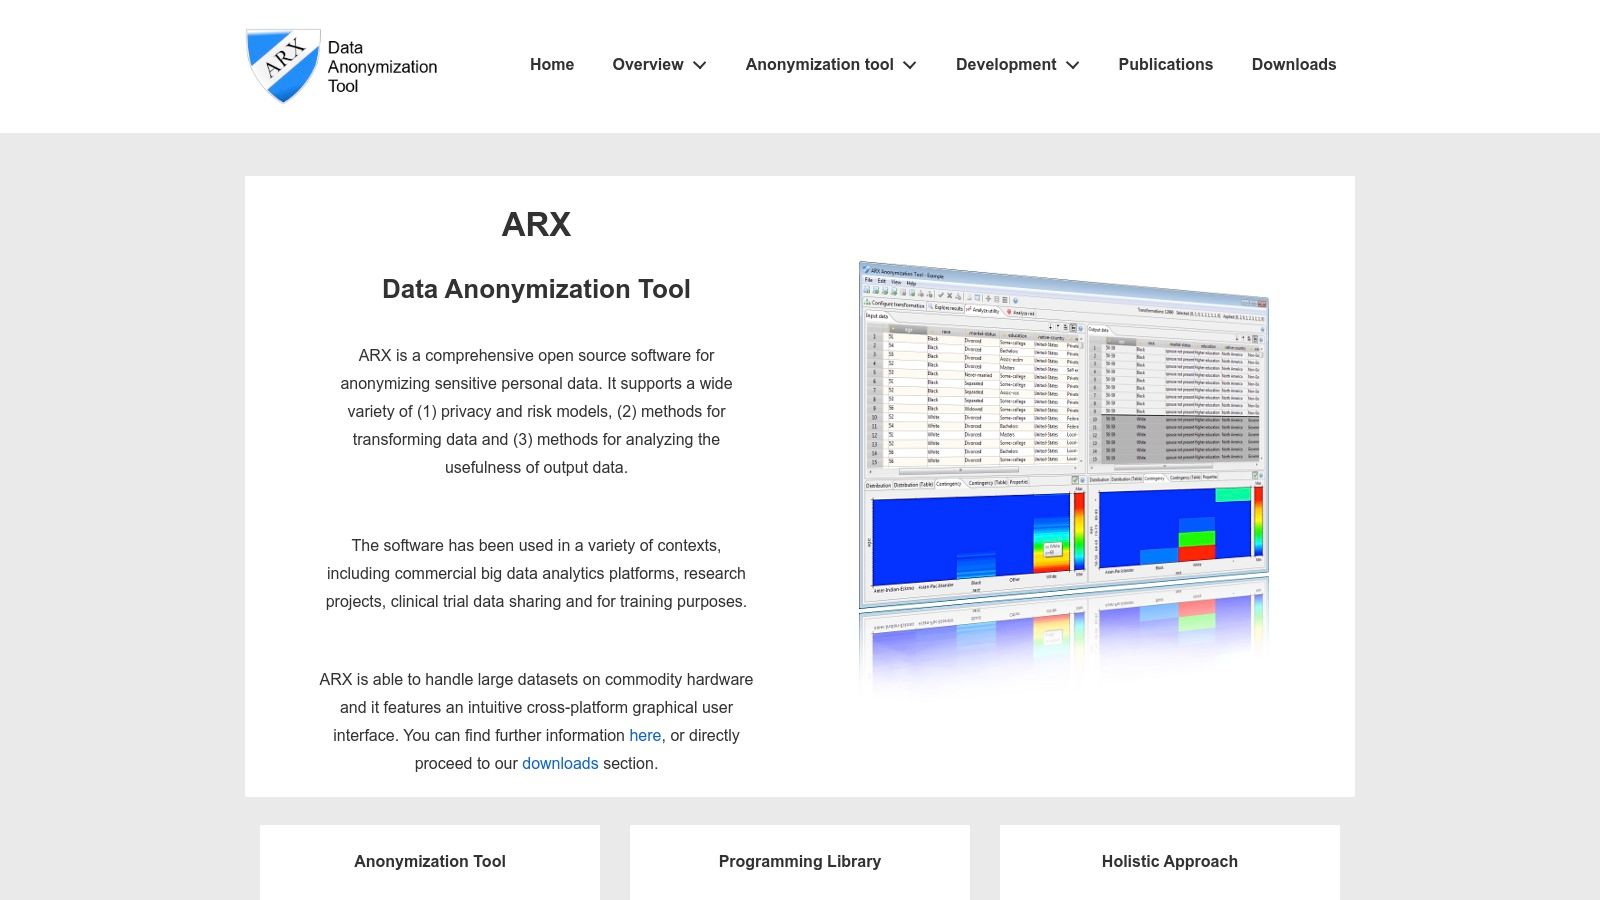
ARX’s strength lies in its implementation of various privacy models, including k-anonymity, l-diversity, t-closeness, and differential privacy algorithms. These models offer different approaches to anonymization, allowing users to choose the best fit for their specific needs and risk tolerance. For instance, k-anonymity ensures that each individual’s record is indistinguishable from at least k-1 other records within the dataset, protecting against identity disclosure. L-diversity further enhances k-anonymity by ensuring diversity within sensitive attributes, preventing attribute disclosure. T-closeness builds upon these by minimizing the difference in the distribution of sensitive attributes between the anonymized dataset and the original dataset. Finally, differential privacy adds noise to the data, making it difficult to infer individual information while preserving statistical properties of the dataset.
Beyond its core anonymization functionalities, ARX provides risk analysis capabilities. Its re-identification risk assessment helps users understand the potential for individuals to be re-identified from anonymized data, allowing them to make informed decisions about the appropriate level of anonymization. The tool also offers data utility analysis, which measures the usefulness of anonymized data for its intended purpose. Balancing privacy and utility matters, and ARX’s built-in metrics help users achieve this balance. Support for hierarchical data transformations allows flexible, granular anonymization of complex data structures.
For developers and IT teams, ARX’s open-source nature is a significant advantage. It allows for customization and integration with existing systems. The active community provides valuable support and resources, ensuring that users can find solutions to any challenges they encounter. ARX requires a Java runtime environment, which is readily available across most platforms.
While ARX boasts a user-friendly GUI, its command-line interface provides advanced users with greater control and scripting capabilities. This makes it a versatile tool suitable for both interactive use and automated data anonymization workflows within larger data pipelines.
One potential drawback of ARX is its scalability limitations with very large datasets. The memory-intensive nature of complex transformations can pose challenges for resource-constrained environments. While improvements are continuously being made, users dealing with extremely large datasets might need to explore alternative solutions or consider distributed processing approaches.
Implementation and Setup Tips:
- Download the latest version: Visit the ARX website (ARX website) and download the appropriate version for your operating system.
- Install Java: Ensure you have a compatible Java Runtime Environment (JRE) installed on your system.
- Follow the tutorials: ARX provides extensive documentation and tutorials that guide users through the anonymization process, from data import to risk analysis and anonymization strategy selection.
- Experiment with different privacy models: Explore the various privacy models offered by ARX and adjust parameters to find the optimal balance between privacy and data utility.
- Monitor resource usage: Keep an eye on memory consumption during complex transformations, especially with large datasets.
ARX is a valuable tool for anyone dealing with sensitive personal data. Its range of features, open-source nature, and user-friendly interface make it a powerful solution for achieving data anonymization and complying with data privacy regulations. While scalability can be a concern for extremely large datasets, ARX remains a strong choice for most anonymization needs, providing a balance of power, flexibility, and ease of use.
2. Privacera
Privacera is an enterprise-grade data security and governance platform designed to address challenges involving data privacy and compliance. It offers tools for data anonymization, masking, and privacy protection, supporting organizations that work with sensitive data across cloud and on-premises environments. The platform features centralized policy management, allowing organizations to define and enforce consistent privacy rules across their data systems. For organizations seeking data anonymization tools, Privacera merits consideration, particularly those managing large-scale data operations and stringent regulatory requirements.
What makes Privacera useful for regulated industries is its focus on turning regulation into a repeatable workflow. A typical governance process involves discovery, classification, policy enforcement, and audit trails: organizations identify sensitive information under obligations such as GDPR, CCPA, or HIPAA, apply relevant masking or anonymization policies, and document enforcement for review. For example, a retailer sharing customer purchase data with an analytics vendor can classify sensitive fields and apply policies to data used for analytics, reducing the need for engineers to hand-write transformations for each dataset.
Privacera is positioned for hybrid and multi-cloud data environments, with support for platforms including Snowflake, AWS, Azure, GCP, and Hadoop. Its centralized policy management can help organizations coordinate governance across those environments, while the suitability and performance of any implementation should be assessed against the customer’s data volumes, architecture, and requirements. Pricing is quote-only and sits in the enterprise tier; budget for implementation services on top of the license. In our review, Privacera’s centralized policy engine is a notable capability for regulated industries, though deployment and configuration may require dedicated data governance resources.
Privacera excels in its ability to handle both dynamic data masking and static data anonymization. Dynamic masking allows real-time obfuscation of sensitive data for authorized users, ensuring that data remains protected while still accessible for legitimate business operations. Static data anonymization, on the other hand, creates a separate, anonymized copy of the data, ideal for development, testing, and analytics purposes without compromising the original sensitive information. This dual capability allows organizations to tailor their data protection strategies to specific use cases, maximizing both security and utility.
A core strength of Privacera lies in its centralized privacy policy management. Through a unified interface, organizations can define granular access controls, masking rules, and anonymization policies, ensuring consistent enforcement across all supported data platforms. This centralized approach simplifies data governance and streamlines compliance efforts, particularly important for organizations operating in heavily regulated industries like finance and healthcare. The platform supports a broad range of data platforms including Hadoop, Snowflake, AWS, Azure, and GCP, enabling organizations to implement a cohesive data security strategy across their hybrid and multi-cloud environments. This interoperability minimizes the need for platform-specific solutions, reducing complexity and management overhead.
Privacera also offers data discovery and classification capabilities. It can automatically scan and classify sensitive data across various data sources, providing organizations with a clear understanding of their data environment and potential vulnerabilities. This real-time visibility empowers organizations to proactively identify and protect sensitive data, mitigating risks associated with data breaches and regulatory non-compliance. By integrating with major data platforms and databases, Privacera supports data protection within existing workflows.
While Privacera offers a powerful suite of tools, it’s important to consider its potential drawbacks. The enterprise-grade features come with enterprise-level pricing, which may be prohibitive for smaller organizations with limited budgets. The initial setup and configuration process can be complex, often requiring dedicated resources and specialized expertise. Ongoing management and maintenance also require dedicated personnel, adding to the overall cost of ownership. Organizations considering Privacera should carefully evaluate their needs and resources to ensure a successful implementation.
Despite these considerations, Privacera’s capabilities and integration ecosystem make it a choice to evaluate for organizations seeking data anonymization and privacy protection. Implementing Privacera effectively requires careful planning, a clear understanding of your data environment, and dedicated resources for configuration and ongoing management. Engage with Privacera’s professional support and services to ensure a smooth implementation and maximize the platform’s potential. For further information and detailed pricing, you can visit their website at Privacera.
3. IBM InfoSphere Optim
IBM InfoSphere Optim is an enterprise data management solution offering data anonymization tools alongside features for test data management, data archiving, and privacy protection. Designed for large-scale enterprise environments grappling with complex data landscapes, InfoSphere Optim provides tools to streamline data operations while safeguarding sensitive information. Its strength lies in its ability to handle large volumes of data from diverse sources, making it a suitable choice for organizations with complex data management needs. This solution supports regulatory compliance and reduces the risk of data breaches by allowing organizations to create realistic yet anonymized test data for application development and testing.
One of the key strengths of InfoSphere Optim is its advanced data masking capabilities. It employs a variety of data anonymization tools and techniques, including substitution, shuffling, perturbation, and encryption, to protect sensitive data while maintaining the statistical integrity of the dataset. This is essential for developing and testing applications in a safe and compliant manner, without risking the exposure of real customer data. For instance, developers can use InfoSphere Optim to create a masked copy of production data for testing new features, ensuring that sensitive information like credit card numbers or social security numbers are replaced with realistic but anonymized values. Similarly, quality assurance teams can use masked data to perform rigorous testing without compromising data privacy.
InfoSphere Optim goes beyond basic data masking by offering test data management functionality. It allows for the creation of realistic and referentially intact test data subsets, empowering development and testing teams to work with data that accurately mirrors the production environment without jeopardizing sensitive information. This capability reduces the time and effort required for test data provisioning, streamlining the development lifecycle. Further enhancing its data management capabilities, InfoSphere Optim provides data archiving and lifecycle management features, enabling organizations to manage the storage and retention of their data.
The platform excels in maintaining referential integrity during the masking process. This ensures that relationships between data across different tables are preserved, maintaining data consistency and usefulness for testing and development. For example, if a customer record is masked in one table, the corresponding order records in related tables will also be masked accordingly, preserving the relationship between the customer and their orders. This feature helps maintain data accuracy and prevent issues during testing and development that can arise from broken relationships. Its integration with the broader IBM data management ecosystem makes it a natural choice for organizations already invested in IBM technology.
While InfoSphere Optim offers a powerful set of features, it’s essential to consider its limitations. As an enterprise-grade solution, it comes with high licensing and implementation costs, making it less accessible to smaller organizations or projects with limited budgets. The complexity of its configuration and maintenance demands specialized skills and may necessitate dedicated administrator training. The learning curve can be steep, requiring substantial investment in training and expertise. Lastly, its strong focus on the IBM technology stack may present integration challenges for organizations operating with heterogeneous environments. Alternative data anonymization tools like Delphix and Data Masker offer comparable features with potentially lower costs and simpler implementations, making them viable alternatives, especially for organizations outside the IBM ecosystem.
Implementation Tips:
- Phased Approach: Implement InfoSphere Optim in phases, focusing on specific use cases initially, like test data management for a particular application.
- Training: Invest in thorough training for administrators to ensure they can effectively configure and manage the platform.
- Collaboration: Foster collaboration between development, testing, and data management teams to leverage InfoSphere Optim effectively.
Technical Requirements & Pricing:
Specific technical requirements and pricing for IBM InfoSphere Optim are not publicly available and are typically obtained through direct engagement with IBM sales representatives. This bespoke approach allows IBM to tailor the solution and pricing to the specific needs and scale of the organization.
More information about IBM InfoSphere Optim can be found on their website.
4. Informatica Persistent Data Masking
Informatica Persistent Data Masking (IPDM) is a powerful data anonymization tool designed for enterprises seeking reliable data protection. It allows organizations to create realistic, yet anonymized copies of their sensitive data for development, testing, training, and analytics purposes, without compromising compliance with data privacy regulations like GDPR, CCPA, and HIPAA. IPDM stands out for its breadth of features, strong enterprise integration capabilities, and focus on compliance. This makes it a valuable addition to the arsenal of any organization dealing with sensitive data. IPDM allows for both static and dynamic masking, meaning it can permanently alter data at rest or provide masked data on the fly, depending on the user or application requesting it. This flexibility caters to a wide range of data protection scenarios.
One of the core strengths of Informatica Persistent Data Masking lies in its extensive library of pre-built masking functions. These functions cover common data types like names, addresses, credit card numbers, social security numbers, and more. This allows users to quickly apply appropriate masking techniques without needing to develop custom scripts. IPDM also supports custom algorithm development for organizations with unique masking requirements. Format-preserving encryption (FPE) is another key feature, enabling data to be masked while retaining its original format. This helps maintain data usability in testing and development environments. For example, a masked credit card number will still look like a credit card number, enabling applications to function correctly without access to real sensitive data. The cross-platform support ensures that IPDM can protect data residing across various database systems, simplifying data masking efforts for organizations with heterogeneous IT infrastructures. IPDM provides detailed audit trails and compliance reporting features, enabling organizations to track masking activities and demonstrate adherence to data privacy regulations.
IPDM shines in enterprise environments due to its strong integration capabilities with other Informatica products and third-party systems. This enables smooth incorporation into existing data management workflows. For instance, IPDM can be integrated with Informatica PowerCenter for data masking during ETL processes or with Informatica Data Quality for data cleansing and standardization before masking. This tight integration simplifies data masking operations and enhances overall data governance.
While IPDM offers a range of features and benefits, it’s essential to be aware of its potential drawbacks. The licensing model can be expensive, particularly for smaller organizations. Implementation can be resource-intensive, requiring specialized expertise and careful planning. Proper training is essential to make full use of IPDM’s capabilities, adding to the overall cost and implementation time.
Practical Applications and Use Cases:
- Application Development and Testing: Providing developers and testers with masked data sets that mimic real data without compromising sensitive information.
- Data Warehousing and Analytics: Creating anonymized data extracts for reporting, business intelligence, and data analysis.
- Training and Education: Equipping training teams with realistic yet safe data sets for educational purposes.
- Outsourcing and Third-Party Sharing: Securely sharing data with external partners and vendors without exposing sensitive customer information.
- Compliance with Data Privacy Regulations: Meeting the data anonymization and pseudonymization requirements of regulations like GDPR, CCPA, and HIPAA.
Implementation and Setup Tips:
- Clearly Define Masking Requirements: Identify sensitive data elements and determine the appropriate masking techniques for each.
- Develop a Comprehensive Masking Strategy: Outline the scope of masking, data sources, masking rules, and implementation timeline.
- Leverage Pre-built Masking Functions: Utilize IPDM’s extensive library of pre-built functions to accelerate implementation.
- Thoroughly Test Masking Procedures: Validate the effectiveness of masking rules and ensure data integrity.
- Monitor and Audit Masking Activities: Regularly review audit trails to track masking operations and ensure compliance.
Pricing and Technical Requirements:
Informatica uses a customized pricing model for IPDM based on specific needs and data volumes. Contacting Informatica directly for a quote is recommended. Technical requirements vary depending on the specific deployment environment and integrations. Detailed information can be found on the Informatica website.
Website: https://www.informatica.com/products/data-security/persistent-data-masking.html
Comparison with Similar Tools
Compared to similar tools like Delphix and Data Masker, Informatica Persistent Data Masking offers a broader range of masking techniques and stronger integration capabilities. Delphix focuses on virtual data copies and rapid provisioning, while Data Masker is known for its ease of use and affordability. Informatica’s extensive feature set and enterprise-grade scalability make it a suitable choice for organizations with complex data masking needs and stringent compliance requirements.
5. Delphix Dynamic Data Platform
Delphix Dynamic Data Platform stands out among data anonymization tools by offering a unique approach to data security and provisioning. Instead of directly masking production data, Delphix creates virtual data copies, significantly reducing storage costs and enabling faster processing. These virtual copies can then be masked and provisioned for various non-production environments, ensuring data privacy while facilitating development, testing, and analytics. This approach addresses the increasing demand for secure data access across the software development lifecycle, making Delphix a valuable tool for organizations prioritizing both speed and security. It’s a particularly strong choice for businesses dealing with large datasets and complex data environments where traditional masking methods might prove cumbersome and slow.
Delphix’s core strength lies in its virtual data copies with integrated masking capabilities. This allows for rapid provisioning of secure data for various teams without impacting the performance or security of the production environment. Imagine needing to set up a test environment with realistic but anonymized customer data. With Delphix, instead of copying and masking the entire production database, which can take hours or even days, a virtual copy can be created and masked quickly. This can accelerate development and testing cycles, helping teams work with protected data.
Delphix provides self-service data provisioning, empowering developers and testers to access anonymized data on demand without requiring intervention from the IT department. Automated masking policy enforcement ensures consistent application of data privacy policies across all virtual copies, simplifying compliance efforts. Real-time data refresh capabilities keep non-production environments up-to-date with minimal downtime, providing development teams with access to current data representations. This level of automation and self-service streamlines workflows and reduces bottlenecks in the development process.
The platform also features API-driven automation and integration, enabling it to connect with existing DevOps toolchains and CI/CD pipelines. This supports a more agile and efficient development environment. For instance, Delphix can be integrated with tools like Jenkins or GitLab to automate the creation and provisioning of masked data for testing as part of the continuous integration process.
While Delphix offers significant advantages, it’s important to consider its potential drawbacks. The initial investment and licensing costs can be high, making it a more viable option for larger enterprises. Its complex architecture requires specialized expertise to implement and manage effectively, which may necessitate dedicated training or the hiring of skilled personnel. Finally, while Delphix supports a wide range of databases and applications, it may have limited support for some legacy systems. Organizations with older infrastructure should carefully evaluate compatibility before committing to Delphix.
Compared to traditional data masking tools that operate directly on production data, Delphix’s virtual data approach offers a different model for provisioning data. While tools like Data Masker and IRI FieldShield are effective for static data masking, they do not offer the same virtual-copy provisioning approach. This distinction matters to organizations requiring frequent access to updated, anonymized data.
For implementation, organizations should first assess their data environment and identify the specific use cases for anonymized data. This will help determine the appropriate licensing and infrastructure requirements. Working with a Delphix certified partner can help streamline the implementation process and ensure proper configuration. Ongoing maintenance and management require specialized expertise, so it’s essential to have dedicated resources or a service agreement in place.
Delphix doesn’t publicly list pricing information, encouraging potential customers to contact their sales team for a customized quote based on their specific needs and usage requirements. This approach allows them to tailor solutions to the individual client, but it also makes it difficult to compare costs upfront without direct engagement.
In conclusion, Delphix Dynamic Data Platform earns its place among the top data anonymization tools due to its virtual data approach, automation capabilities, and focus on data provisioning. While it represents a significant investment, the benefits of development workflows, data security, and storage management can be substantial for organizations with demanding data provisioning needs. For software developers, QA engineers, and DevOps professionals dealing with large datasets and complex data environments, Delphix offers a powerful and efficient solution for secure data access and management. You can explore their offerings further on their website: Delphix
6. Microsoft SQL Server Data Masking
Microsoft SQL Server Data Masking offers a straightforward, integrated solution for protecting sensitive data within your SQL Server databases. This built-in feature provides real-time, dynamic data obfuscation, allowing developers, testers, and other authorized personnel to work with realistic data sets without exposing actual sensitive information. This capability is particularly valuable for non-production environments like development, testing, training, and reporting, where access to real data is necessary but the risk of exposure needs to be mitigated. This tool is particularly beneficial for adhering to data privacy regulations like GDPR, CCPA, and HIPAA when used as part of an appropriate data protection strategy. It makes SQL Server Data Masking a convenient tool for organizations already utilizing the SQL Server ecosystem, streamlining data anonymization efforts and reducing the need for complex third-party solutions.
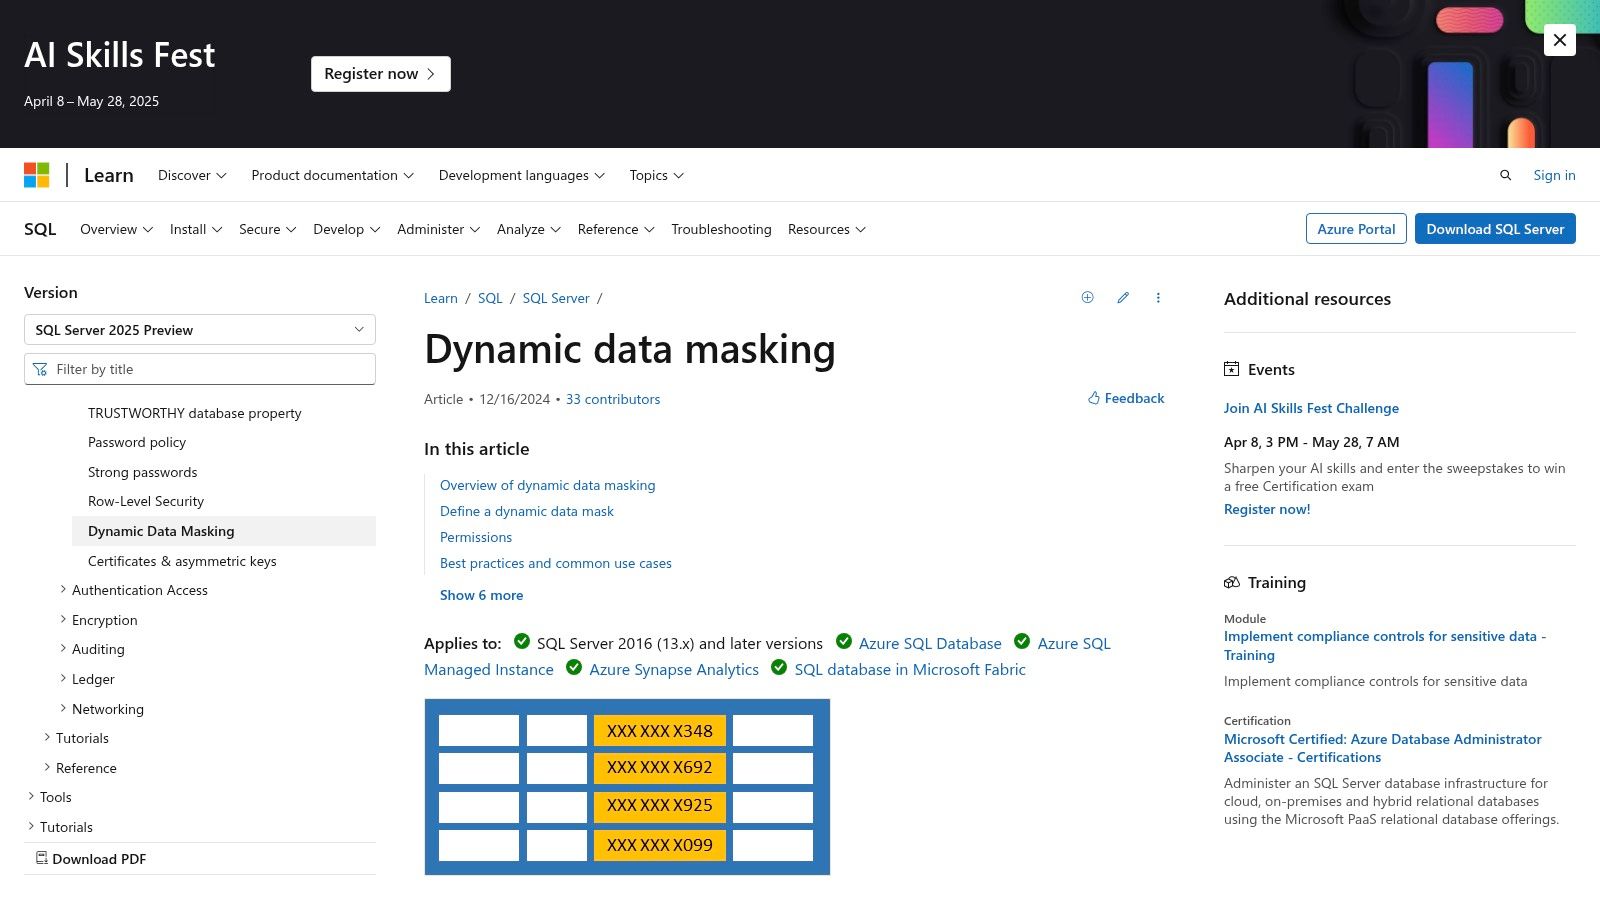
One of the key advantages of SQL Server Data Masking is its close integration with the existing SQL Server security model. Masking rules are applied at the column level and managed through SQL Server Management Studio (SSMS), a familiar interface for SQL Server administrators. This integration simplifies the setup and configuration process significantly. Administrators can define masking policies based on user roles and permissions, ensuring that sensitive data is only revealed to authorized individuals. For instance, a developer might see masked credit card numbers while a customer service representative can access the full, unmasked information. This granular control over data access enhances security and streamlines compliance efforts.
SQL Server Data Masking uses a set of built-in masking functions to obfuscate data. These functions include:
- Full masking: Replaces the entire value with a specific character, like ‘X’ or ’#’.
- Partial masking: Reveals only a portion of the data, such as the last four digits of a credit card number.
- Random data generation: Substitutes sensitive values with randomly generated data of the same data type, maintaining data integrity for testing purposes.
- Date shifting: Alters date values by a specific offset while preserving the date format.
- Email masking: Protects email addresses by replacing characters with ‘X’ while retaining the domain name.
While these functions offer a good starting point for basic data masking, they provide fewer capabilities than specialized data anonymization tools. This limitation can constrain organizations with complex masking requirements or needs for advanced techniques like format-preserving encryption or tokenization.
The primary advantage of SQL Server Data Masking lies in its inclusion with existing SQL Server licensing. This means no additional costs for organizations already using SQL Server. It is straightforward to implement and requires no separate infrastructure. However, its limitation to SQL Server environments and dynamic-only masking capabilities restricts its broader applicability across diverse database systems and static data masking needs. Other tools offer more extensive masking techniques and cross-platform support, making them more suitable for organizations with complex requirements or heterogeneous database landscapes. Despite these limitations, SQL Server Data Masking remains a valuable data anonymization tool for organizations heavily reliant on the SQL Server ecosystem, offering a quick, simple, and cost-effective way to protect sensitive information within their SQL Server databases.
For implementing data masking in SQL Server, consider these tips:
- Identify sensitive data: Clearly define which columns require masking based on regulatory requirements and internal policies.
- Choose appropriate masking functions: Select the function that best suits the data type and desired level of obfuscation.
- Test thoroughly: Verify that the masking rules are working as expected and do not impact application functionality.
- Monitor and audit: Regularly review masking policies and audit data access to ensure ongoing compliance.
For further information and detailed documentation, refer to the official Microsoft documentation: Microsoft documentation
7. MOSTLY AI
MOSTLY AI distinguishes itself in the realm of data anonymization tools by offering a synthetic data platform. Instead of directly modifying sensitive data, MOSTLY AI uses machine learning techniques to generate artificial datasets that statistically mirror the original data while aiming to protect privacy. This approach supports data sharing, analytics, and machine learning model development without exposing the original records.
For AI teams, synthetic data can offer value when it retains useful statistical patterns from the source dataset. Before relying on a synthetic dataset, compare its utility with the original for the intended task, including distributions, relationships, and downstream model performance. Synthetic data may not preserve every edge case or relationship, so teams should evaluate whether it suits their specific use. For analytics reporting, a business intelligence team could use synthetic customer data with a similar structure for dashboards, limiting the need to expose raw personal information to every analyst.
MOSTLY AI supports various data types, including tabular, time-series, and mixed data, broadening its application across diverse domains. For example, in the financial sector, it can be used to generate synthetic transaction data for fraud detection model training. In healthcare, it can create synthetic patient records for research and development purposes, preserving patient confidentiality. Similarly, retail companies can use MOSTLY AI to generate synthetic customer data for personalized marketing campaigns without revealing individual customer details.
The platform is cloud-based and provides API access, facilitating integration with existing data pipelines and workflows. This can help organizations incorporate synthetic data into their processes. The cloud-based architecture also reduces the need for on-premise infrastructure.
For software developers, QA engineers, and DevOps professionals, synthetic data can provide an alternative source of data for test environments, supporting software development and testing without directly exposing sensitive production records.
Enterprise IT teams and tech-savvy business leaders can also consider synthetic datasets when sharing data with partners. The approach can support collaboration and analytics while limiting exposure of personal information, subject to validation for the intended use and applicable privacy requirements.
MOSTLY AI’s privacy approach uses techniques intended to reduce the risk of individual data points being reconstructed from synthetic data. Pricing follows a subscription model, with details available on request from Mostly AI directly. Users also need some familiarity with synthetic data concepts to define the statistical properties and relationships they want preserved — achieving useful results requires careful consideration of the specific data and use case.
Use cases requiring strict data fidelity or precise, per-value transformations might be better addressed by data masking or pseudonymization. The platform provides controls over data generation, but users have limited direct influence over the specific transformations applied to individual data points. You can explore their platform and offerings further at MOSTLY AI.
8. Oracle Data Masking and Subsetting
Oracle Data Masking and Subsetting is an enterprise solution for data anonymization and test data management within Oracle environments. It allows organizations to create realistic, anonymized copies of their production data for development, testing, training, and reporting without compromising sensitive information. Its integration with the Oracle ecosystem offers a familiar experience for users already working within that environment.
One of the core strengths of Oracle Data Masking and Subsetting lies in its extensive library of pre-defined masking formats. These formats cover a wide range of data types, including names, addresses, credit card numbers, social security numbers, and dates. For unique data masking requirements, the tool supports the development of custom masking functions using PL/SQL, providing flexibility and control over the anonymization process.
The tool also excels in maintaining referential integrity. When masking related data across multiple tables, relationships remain consistent — if a customer ID is masked in one table, it is masked identically across all related tables. The integrated data subsetting capabilities further reduce storage costs and processing time for non-production environments.
The practical drawbacks deserve an honest accounting, however. Licensing is tied to Oracle Enterprise Manager and the underlying Oracle Database edition, so the effective cost may be a concern for organizations not already running the Oracle stack. Its positioning is centered on Oracle environments, so buyers with multi-vendor environments should assess how it fits alongside their other database systems. The custom-function path assumes PL/SQL competence.
On integration: for Oracle-centric shops, the tool slots into existing Oracle Database and Enterprise Manager workflows, which can simplify implementation. Heterogeneous shops should consider whether maintaining a separate Oracle masking tool alongside other solutions fits their needs; a cross-platform solution like Informatica IPDM or Delphix may be more consistent. Our verdict: if Oracle Database is your primary production platform and your DBA team already lives in Enterprise Manager, this is a path to consider for anonymization; otherwise, compare cross-platform options first.
Practical Applications & Use Cases:
- Application Development: Create realistic test data for new application development and bug fixing without exposing real customer data.
- QA Testing: Generate masked datasets for performance and functional testing.
- Training: Prepare masked datasets for training activities.
- Performance: Use masked datasets for performance testing.
- Reporting and Analytics: Create masked datasets for reporting and business intelligence.
- Compliance with Data Privacy Regulations: Anonymize sensitive data before sharing it with third parties or using it for non-production purposes.
Implementation Tips:
- Analyze data sensitivity: Identify sensitive information requiring masking before implementing.
- Plan masking formats: Carefully select appropriate masking formats for each data type.
- Test thoroughly: Rigorously test masked data to ensure accuracy and referential consistency.
- Monitor performance: Monitor performance during masking and subsetting processes.
Pricing and Technical Requirements: Pricing for Oracle Data Masking and Subsetting is typically tied to the Oracle Database edition and licensing model. Technical requirements include an Oracle Database instance and sufficient system resources to handle the masking and subsetting processes. Contact Oracle sales for detailed pricing based on your environment. Details are available on the Website.
Wherever you land on this list, your next steps depend on your buyer profile: compliance-first enterprises should assess Privacera and Informatica; AI and analytics teams should pilot synthetic generation with MOSTLY AI and validate utility on a relevant dataset before committing; dev/QA teams can start by evaluating ARX or SQL Server Data Masking, and consider Delphix when virtual data provisioning fits their needs.
Data Anonymization Tools Comparison
The comparison table at the beginning of this article is the primary decision aid for comparing features and pricing. For a wider view of the adjacent privacy-tooling market, see more from Freeform Company.
| Tool | Core Features/Capabilities | User Experience/Quality ★ | Value Proposition 💰 | Target Audience 👥 | Unique Selling Points ✨ |
|---|---|---|---|---|---|
| ARX Data Anonymization Tool | k-anonymity, differential privacy, GUI | ★★★★⭐ User-friendly GUI | 💰 Free, open-source | 👥 Non-technical users, researchers | ✨ Extensive privacy models, compliance support |
| Privacera | Dynamic masking, policy management, multi-cloud | ★★★★⭐ Enterprise reliable | 💰 Enterprise priced | 👥 Large enterprises | ✨ Centralized policy management, strong integrations |
| IBM InfoSphere Optim | Advanced masking, test data mgmt, archiving | ★★★★⭐ Enterprise-grade | 💰 High licensing | 👥 Large enterprises w/ IBM stack | ✨ Strong referential integrity, lifecycle mgmt |
| Informatica Persistent Masking | Static/dynamic masking, FPE, audit trails | ★★★★⭐ Enterprise focused | 💰 Expensive licensing | 👥 Enterprises requiring compliance | ✨ Pre-built masking library, compliance features |
| Delphix Dynamic Data Platform | Virtual data copies, self-service provisioning | ★★★★⭐ Fast, automated | 💰 High investment | 👥 Enterprises needing fast data | ✨ Virtual copies reduce storage, API-driven |
| Microsoft SQL Server Masking | Built-in dynamic masking, policy-based rules | ★★★⭐ Easy integration | 💰 Included with SQL Server | 👥 SQL Server users | ✨ No app changes needed, simple setup |
| MOSTLY AI | Synthetic data with differential privacy | ★★★★⭐ High data quality | 💰 Subscription-based | 👥 Data scientists, ML teams | ✨ AI-powered synthetic data, strong privacy |
| Oracle Data Masking & Subsetting | Pre-defined masks, data subsetting, referential integrity | ★★★★⭐ Enterprise performance | 💰 High licensing cost | 👥 Oracle ecosystem users | ✨ Deep Oracle integration, enterprise security |
Choosing the Right Data Anonymization Tool
The “best” tool depends entirely on your specific needs. The most important factors include the type and sensitivity of the data you’re protecting, your budget, your team’s technical expertise, and the level of compliance you need to achieve. Don’t forget to factor in ongoing maintenance and support requirements. Carefully evaluating these aspects against the capabilities of each tool will help you protect sensitive data without hindering business operations.
Successfully anonymizing data is critical, but ensuring your applications function correctly with this anonymized data is equally vital. Enhance your testing strategy by integrating a tool like GoReplay with your chosen anonymization solution. GoReplay allows you to capture and replay real-world traffic against your anonymized test environments, providing realistic and secure testing without risking sensitive production data. Learn more about how GoReplay can enhance your data anonymization workflow by visiting GoReplay.
Frequently Asked Questions
What is the difference between data masking and data anonymization?
Data masking replaces sensitive values with altered versions of the data, which may or may not be reversible — dynamic masking, for example, shows masked output while the real data remains intact underneath. Data anonymization aims to make re-identification more difficult, typically through irreversible transformation or synthetic generation. Tools like Privacera and Informatica handle masking; MOSTLY AI and ARX use synthetic generation and privacy models like k-anonymity.
What is anonymized and aggregated data?
Anonymized data has had direct and indirect identifiers removed or transformed so individuals can’t be singled out. Aggregated data summarizes records into counts, averages, or distributions rather than row-level entries. Aggregation can strengthen privacy, but it removes row-level detail that tools like ARX and MOSTLY AI may preserve for testing and model training purposes.
Which data anonymization tool is best for large enterprise databases?
For large enterprise estates, Privacera and Informatica Persistent Data Masking are options to assess for policy enforcement and compliance reporting, while Delphix focuses on virtual data copies and provisioning. In our review, Privacera is worth considering for regulated environments, while Oracle’s offering is positioned around Oracle environments. Compare each tool against your database landscape, implementation needs, and budget.
Can anonymized data be used for AI training and analytics?
Yes. Synthetic data can support AI training and analytics when it retains useful statistical patterns for the intended task. MOSTLY AI focuses on synthetic datasets, while masked data may suit use cases needing greater fidelity to source records. Validate downstream model performance and privacy requirements before replacing real data entirely.